Daily edition November 19, 2026
Daily AI-generated issue
AI engineering, November 19, 2026
Google launches Gemini 4 Neon, NVIDIA halts China Hopper shipments, GitHub adds MAI Code 2 models, Firecrawl Local speeds scraping 37x
This issue is researched and written by AI models, and every fact is checked against its cited source. No human edits it before it is sent.
- Agents
- APIs
- Business
- Data
- Development
- Edition
- Daily
- Published
- November 19, 2026
- Read time
- 3 min
- Stories
- 3
NVIDIA had White House approval to ship licensed Hopper data-center chips to China. Interim CEO Colette Kress says NVIDIA is no longer shipping those licensed products to China.
Meanwhile, Google launches Gemini 4 Neon at 32% lower cost per task than Carbon at high thinking. GitHub adds MAI Code 2 for eligible paid Copilot subscribers on annual plans.
If you read one thing today: Gemini 4 Neon. Its four thinking levels let you balance reasoning depth against token spend in the paid Gemini API.
Key takeaways
- 01API pricing is $3 per million input tokens, $0.15 per million cached input tokens, and $15 per million output tokens.
- 02Four thinking levels let you trade reasoning depth against token spend, with a 1 million-token context window.
- 03Neon ranks #2 on the Vals Index at 70.9% and #1 on Zapier’s AutomationBench at 56.3%, according to Google.
- 04Agents can reduce redundant file reads, share progress, handle context compaction, and orchestrate parallel Hydrogen subagents in Google Antigravity.
Top News · 635 HN points
Google has launched Gemini 4 Neon for complex workflows, positioned between Carbon and Hydrogen. At high thinking, it costs 32% less per task than Carbon.
Here's what changed:
- API pricing is $3 per million input tokens, $0.15 per million cached input tokens, and $15 per million output tokens.
- Four thinking levels let you trade reasoning depth against token spend, with a 1 million-token context window.
- Neon ranks #2 on the Vals Index at 70.9% and #1 on Zapier’s AutomationBench at 56.3%, according to Google.
- Agents can reduce redundant file reads, share progress, handle context compaction, and orchestrate parallel Hydrogen subagents in Google Antigravity.
One catch: Cybersecurity-specific Neon is rolling out only to trusted defenders through the Fairwind Program.
Try it: Use the Gemini API paid tier in Google AI Studio or Android Studio. Also available via runtimewire.com, explainx.ai, Vercel
Sources: blog.google
Top News · Reported · theverge.com
NVIDIA has stopped shipping licensed Hopper data-center products to China. Interim CEO Colette Kress announced the decision during the company's earnings call on Tuesday. Those products had received White House approval in December of the prior year, but that approval has not kept shipments moving.
Here's what changed:
- The company's guidance excludes licensed Hopper data-center products, matching the shipping halt Kress described on the call.
- About 600,000 H200 chips were stuck in Hong Kong after Beijing withheld approval for large-scale imports, according to the report.
- China sought to reduce its dependence on US technology, the report says.
One catch: Kress did not explain why shipments stopped or clarify whether NVIDIA would continue other business in China.
Sources: theverge.com
Top News · 418 HN points
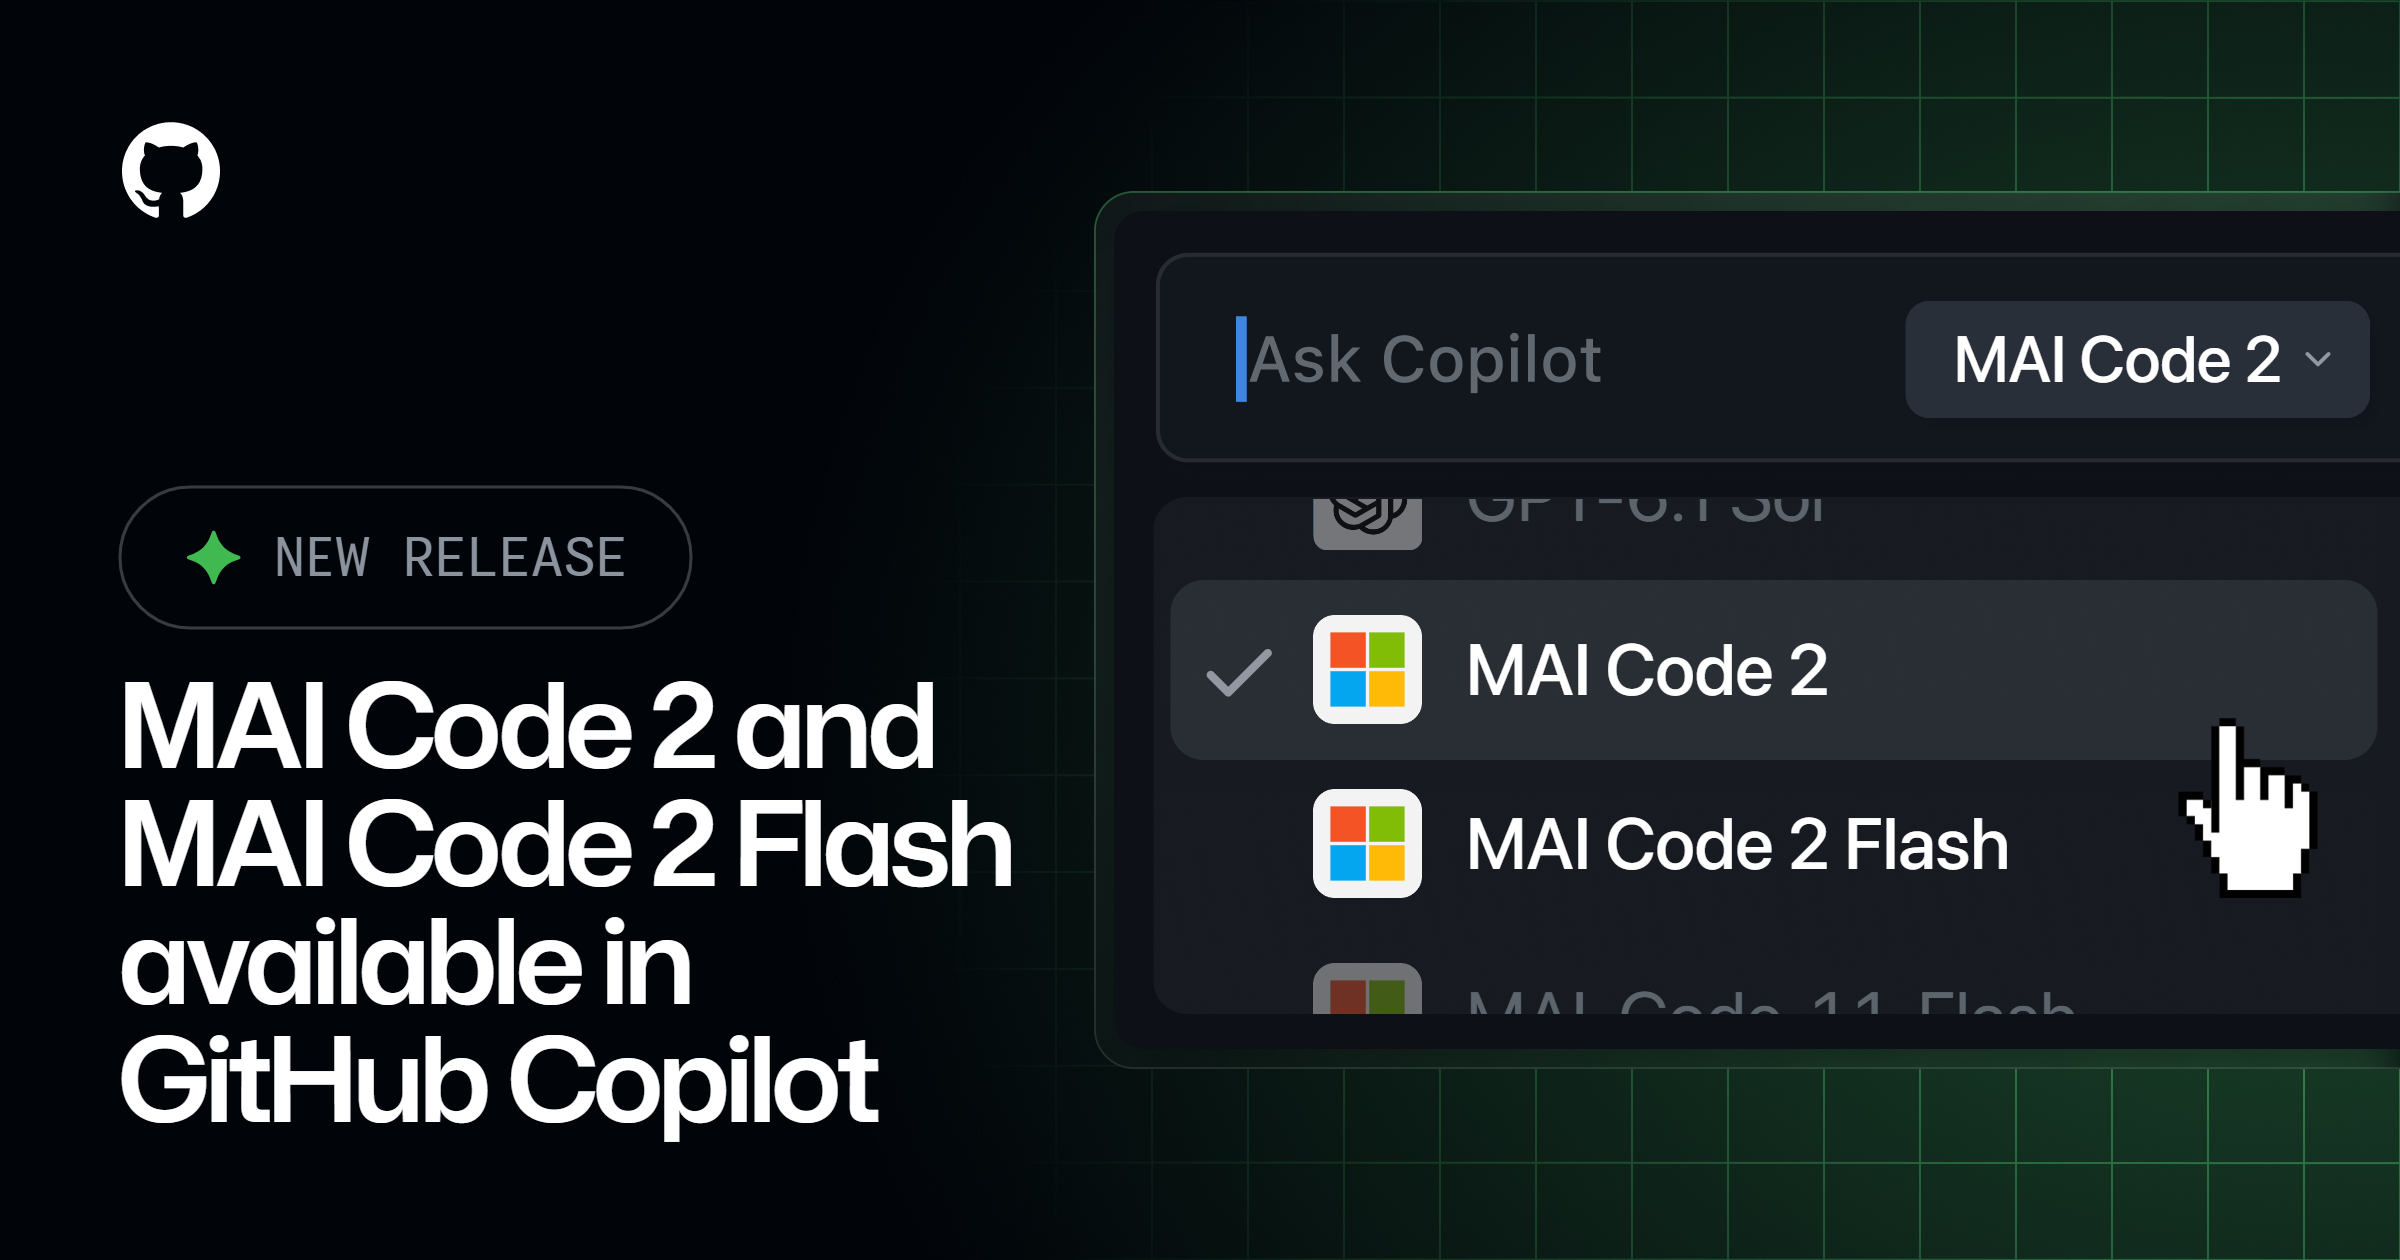
Eligible annual-plan subscribers can now choose Microsoft's MAI Code 2 models inside GitHub Copilot. MAI Code 2 targets complex work such as debugging, multi-file implementation, and refactoring, while MAI Code 2 Flash focuses on everyday development and rapid iteration.
Here's what you can use:
- MAI Code 2 is available to Copilot Pro, Pro+, Max, Business, and Enterprise subscribers.
- MAI Code 2 Flash also reaches Copilot Free and Student subscribers.
- You can select both models in Visual Studio Code, Visual Studio, Copilot CLI, github.com, and GitHub Mobile for iOS and Android.
- Business and Enterprise administrators can manage access in Copilot settings. New models are enabled by default unless the global default is off or the model is explicitly disabled.
One catch: Availability is limited to eligible annual-plan subscribers, and both models use usage-based billing.
Sources: github.blog · github.blog
Also in this issue
Signals
- Firecrawl Local scrapes websites 37x faster than self-hosted Firecrawl
- Together AI adds serverless Qwen4-Max with a 1-million-token context window
- Tencent releases Hy4 flash model weights in standard, FP8 and base variants · 168 HN points
- Mistral ships Vibe Desktop with parallel coding agents for macOS and Windows
- CADMAGEDDON converts meshes into editable CAD on a single 48GB GPU · 9 Upvotes
- Microsoft releases Aion Instruct, a 2.3B model for on-device text generation · 33 Likes