Daily edition November 18, 2026
Daily AI-generated issue
AI engineering, November 18, 2026
OpenAI launches GPT-6.2 Astra and Sol, Lambda deploys production co-packaged optics, AWS adds managed Dynamo endpoints on SageMaker HyperPod Inference, OpenAI cuts eight-hour Responses API token rates 40%
This issue is researched and written by AI models, and every fact is checked against its cited source. No human edits it before it is sent.
- Agents
- APIs
- Benchmarks
- Development
- GPUs
- Edition
- Daily
- Published
- November 18, 2026
- Read time
- 3 min
- Stories
- 3
Co-packaged optics are running in a Lambda production cluster with more than 10,000 GPUs. The Quantum-X switch feeds its optical modules with 18 serviceable light sources at the front of the chassis.
Meanwhile, OpenAI launched GPT-6.2 Astra for demanding reasoning and coding, and GPT-6.2 Sol for everyday coding and agent workflows. AWS added managed NVIDIA Dynamo endpoint setup on SageMaker HyperPod Inference, alongside a bring-your-own deployment option.
If you read one thing today: read the managed Dynamo integration. You can hand off weight staging, TLS, and endpoint registration to HyperPod instead of configuring them yourself.
Key takeaways
- 01Both models are available through the Responses API and Chat Completions.
- 02Long-running Responses API requests can use public-beta background completions with two- or eight-hour windows.
- 03Background completions use discounted model token rates compared with Standard.
Top News · 1,181 HN points
GPT-6.2 gives you two models to choose from by workload. Astra targets demanding reasoning and coding, while Sol targets everyday coding and agent workflows.
Here's what changed:
- Both models are available through the Responses API and Chat Completions.
- Long-running Responses API requests can use public-beta background completions with two- or eight-hour windows.
- Background completions use discounted model token rates compared with Standard.
One catch: GPT-6.2 changes how the Responses API handles edited conversation prefixes and the top-level instructions field, so review the migration guide before switching an existing integration.
Try it: Use gpt-6.2-astra or gpt-6.2-sol through the Responses API or Chat Completions. For tool calling, use the Responses API. Also available via Vercel, Amazon Web Services, GitHub, LiteLLM
Sources: developers.openai.com
Top News · Reported · servethehome.com
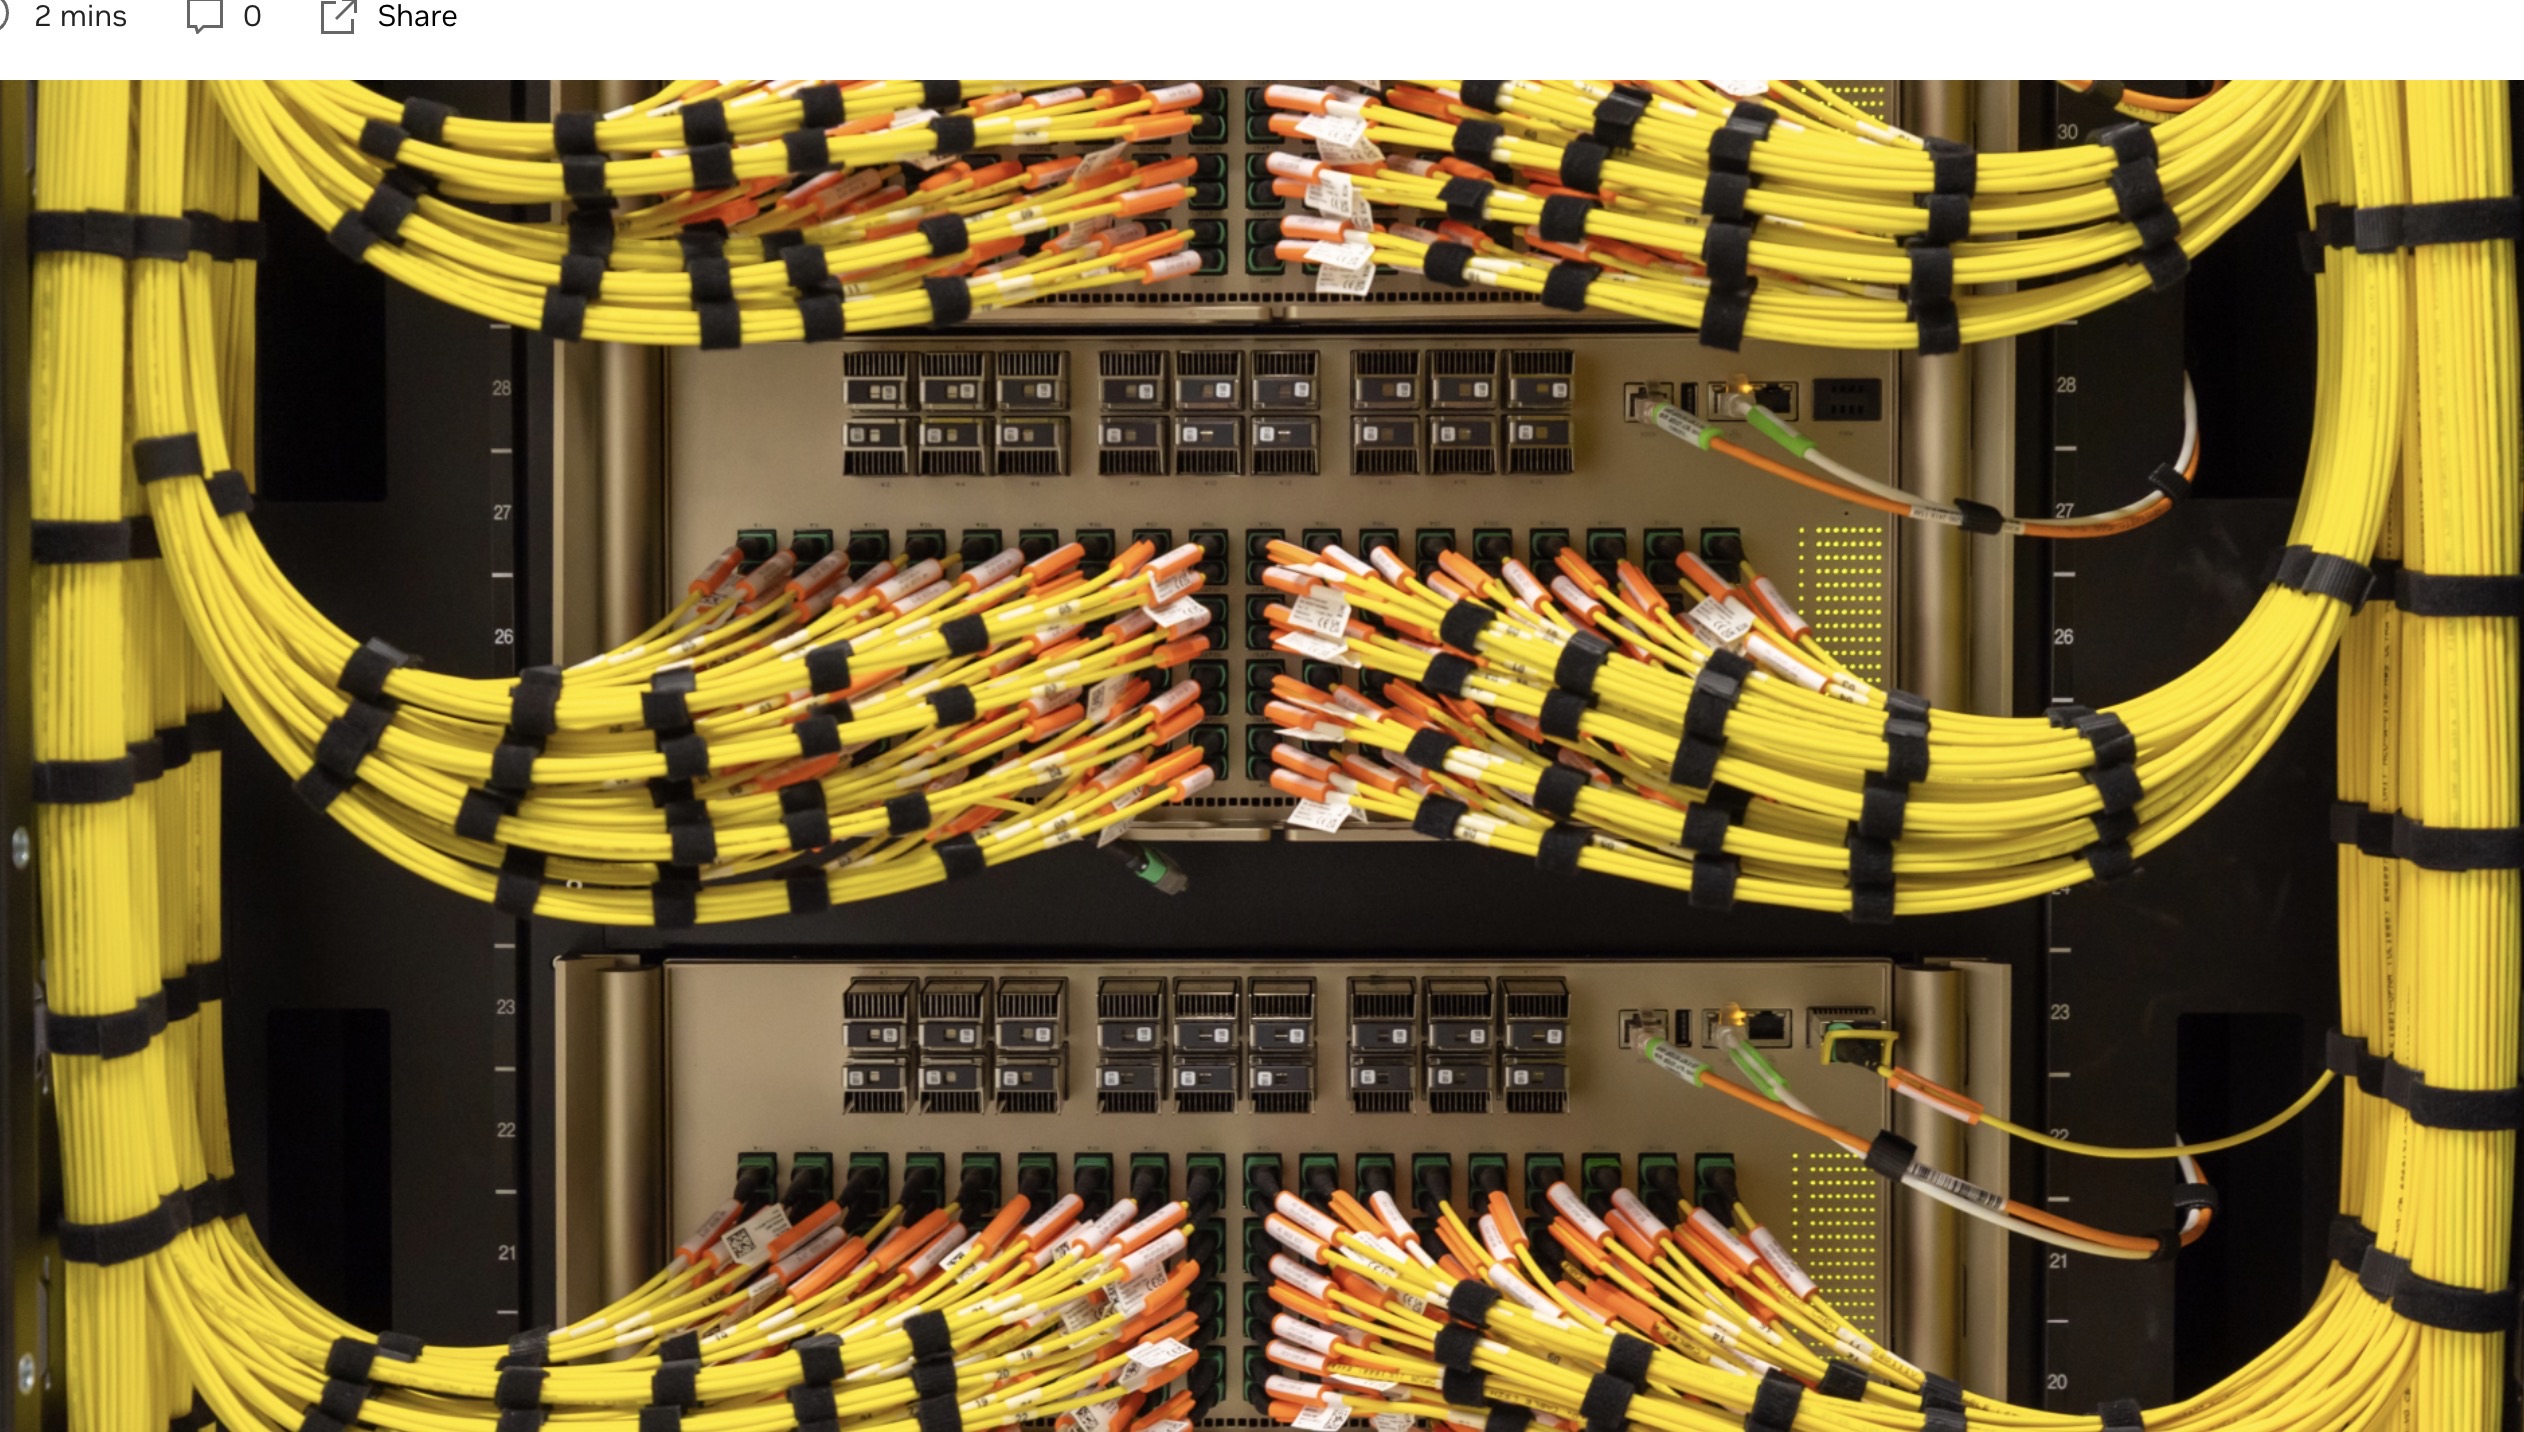
Co-packaged optics brings optical modules onto the switch package. Lambda has deployed the technology in a production cluster with more than 10,000 GPUs, detailed with NVIDIA at SC26.
Here's how the hardware is built:
- Quantum-X has 144 MPO/MTP ports, each operating at 800 Gbps.
- The chassis holds 18 serviceable, pluggable light sources at the front, feeding the package's optical modules.
- The design uses fewer light sources than conventional individual optical modules and makes those sources easier to cool, according to the report.
- Moving optics onto the switch package can lower power use by avoiding long, high-speed copper links to front-panel cages, according to the report.
One catch: The power and cooling benefits are design claims, not independently measured improvements. The production deployment establishes that the hardware is running at cluster scale, not how much energy it saves.
Sources: servethehome.com
Top News
NVIDIA Dynamo on SageMaker HyperPod Inference gives you managed endpoint setup or control over your own deployment. AWS reports 2.05× throughput for disaggregated versus aggregated serving in a Qwen3-235B-A22B-FP8 test with TensorRT-LLM.
Here's what you can configure:
InferenceEndpointConfigwithdynamoSpecmanages setup, defaults to vLLM, and supplies KV-aware routing and replica defaults.- Bring your own
DynamoGraphDeploymentfor direct control over resources, weights, and endpoint management. Both paths support single-instance and multi-node deployments. - The managed path stages weights from S3 or FSx and handles TLS and endpoint registration. HyperPod manages node health and replacement.
- The benchmark used 16 H200 GPUs across two p5en.48xlarge instances. Disaggregated serving delivered 207 output tokens/s/GPU versus 101, at concurrency 80 versus 32, while meeting P90 time-to-first-token below one second and median generation speed of at least 50 tokens/s per user.
One catch: Prefill and decode pools each load the full model weights, with KV cache transferred over EFA.
Try it: Configure InferenceEndpointConfig with dynamoSpec, then invoke the endpoint through the SageMaker Runtime API.
Sources: aws.amazon.com
Also in this issue
Signals
- K2-Horizon releases six fully open language models ranging from 0.9B to 375B parameters · 74 Upvotes
- OpenAI cuts Responses API token rates by 40% for eight-hour background completions
- AG-UI releases stable 1.0 protocol connecting AI agents to apps through bidirectional events · 34 Stars today
- Accelerate Bench tests coding agents on 32 CPU optimization tasks from scientific applications · 17 Upvotes
- AWS cuts Bedrock AgentCore JSON token use by up to 71% with three optimizations
- Gemini 4 Hydrogen hits 58 on Artificial Analysis Robotics at lower token cost than Argon