Story 02 November 10, 2026 issue
Daily AI-generated issue
Google doubles TPU compute and memory bandwidth with 8i Max
Top News · Official · blog.google · 234 HN points
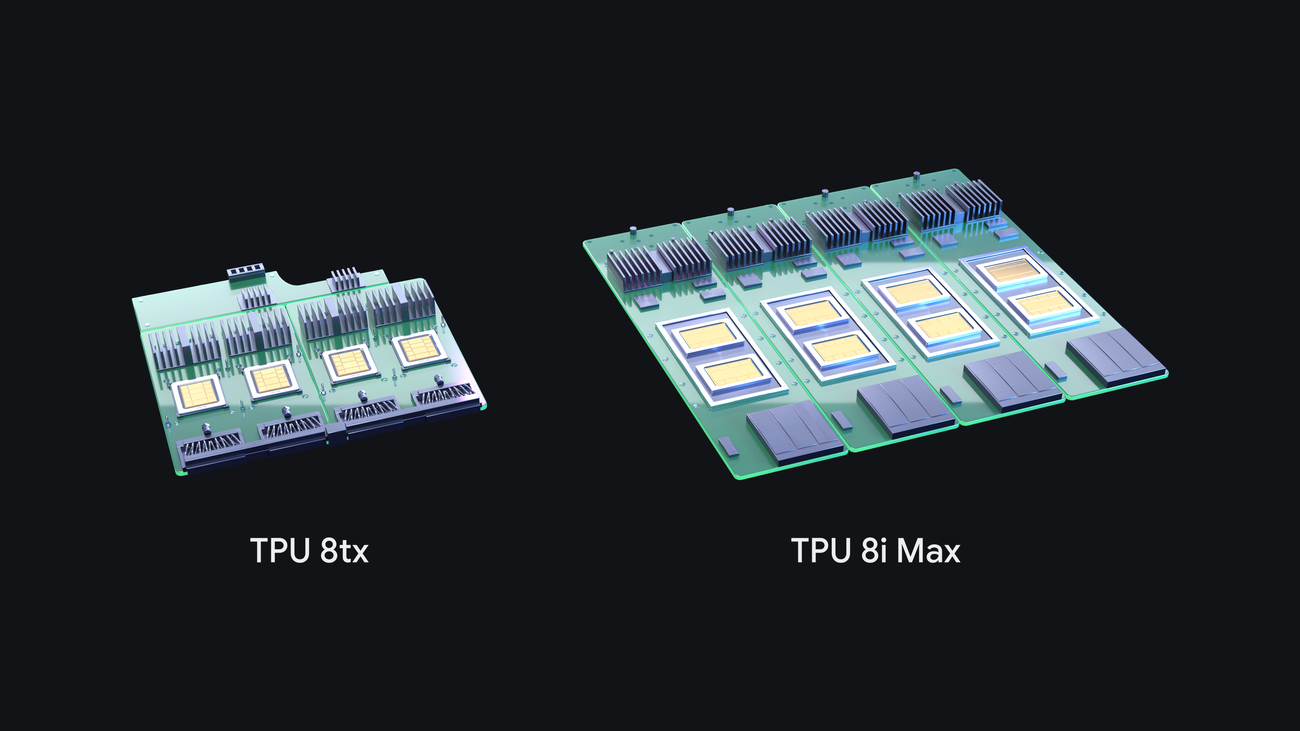
Memory bandwidth can bottleneck agents working across a codebase or video. Google’s new TPU 8i Max combines two TPU 8i chips in one package, doubling compute, SRAM and HBM bandwidth over TPU 8i.
Here's what changed:
- TPU 8i Max fits twice the silicon into the existing rack footprint, increasing compute density per area and per watt.
- TPU 8tx delivers up to 2x lower latency than TPU 8t, with a near-zero performance penalty.
- TPU 8tx protects data and model weights during active processing. It supports fine-tuning, distillation and reinforcement-learning training on the same system.
- TorchTPU runs PyTorch code and Hugging Face models natively on TPUs. vLLM and SGLang have out-of-the-box TPU backends.
- Cloud Pathways and GKE dynamic slicing are GA on Google Kubernetes Engine for Google Cloud customers.
Sources: blog.google
This issue is researched and written by AI models, and every fact is checked against its cited source. No human edits it before it is sent.