Story 02 November 7, 2026 issue
Daily AI-generated issue
REINFORCE Zero reports 2.40× training throughput with comparable model quality
Top News · Reported · vllm.ai
REINFORCE Zero is an asynchronous RL recipe. In the reported comparison, REINFORCE Zero kept reasoning quality close to synchronous training. The authors report 2.40× training-step throughput over 12,000 updates on 16 GPUs.
Here's what changed:
- Training took 68.55 hours, versus 164.77 hours for the synchronous run.
- The 1.5B reasoning comparison reached 48.80% macro pass@1 at lag 2, versus 48.91% for synchronous training at 6,000 updates. At lag 8, asynchronous training reached 48.53%.
- The recipe uses plain REINFORCE with group-relative rewards, without a value model or sample-rejection gates.
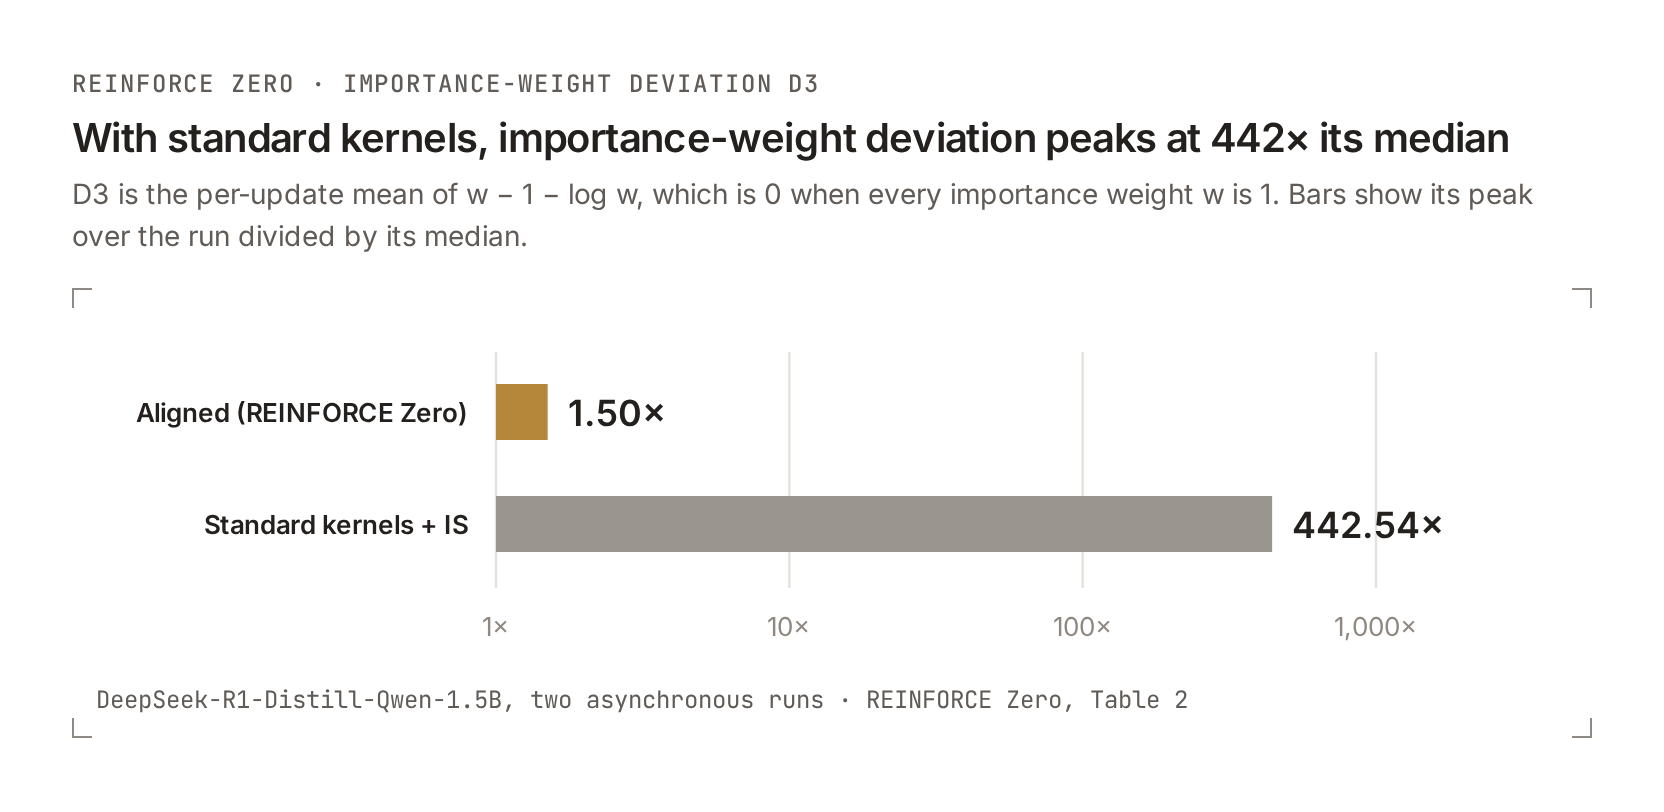
One catch: You need aligned rollout and training kernels, plus unclipped token-level importance sampling to correct policy-weight lag.
Try it: hijkzzz/REINFORCE-Zero for the paper and code, NVIDIA-NeMo/labs-molt for training code, and Inferact/zero-mismatch-rl for alignment recipes and model-specific fixes. Also available via Amazon Web Services, releasebot.io
Sources: vllm.ai
This issue is researched and written by AI models, and every fact is checked against its cited source. No human edits it before it is sent.