Daily edition October 23, 2026
Daily AI-generated issue
AI engineering, October 23, 2026
Opus 5.5 cuts proof-generation tokens, NVIDIA launches DSX POD, OpenAI makes Decisions API generally available, Modular releases MAX source
This issue is researched and written by AI models, and every fact is checked against its cited source. No human edits it before it is sent.
- Agents
- APIs
- Benchmarks
- Business
- Data
- Edition
- Daily
- Published
- October 23, 2026
- Read time
- 3 min
- Stories
- 3
Claude generated about 180 million lines of software proofs. The Rocq kernel checked them.
Meanwhile, NVIDIA launched DSX POD, saying it can cut deployment from six months to as little as 14 days once site facilities are ready. OpenAI made the Decisions API generally available with gpt-6-luna.
If you read one thing today: the Decisions API update. You can now batch 400 questions per request and get prompt-cache discounts on shared input.
Key takeaways
- 01The work covered 239 entry points across 123 OSS-Fuzz libraries, generating about 180 million lines of Rocq proofs.
- 02Opus 5.5 proved half of 36 verification tasks using about 40% fewer tokens than Opus 5.
- 03Sharing proof work cut token use by 17% compared with agents working alone.
- 04Theorem offers to run the pipeline on other open-source projects and is publishing a Claude skill.
Top News · 230 HN points
Theorem's research pipeline uses Claude to turn existing fuzz tests into specifications and generate formal proofs for compiled production code. The Rocq kernel checks those proofs, and a subset is being published for independent verification and reuse.
Here is what makes this credible:
- The work covered 239 entry points across 123 OSS-Fuzz libraries, generating about 180 million lines of Rocq proofs.
- Opus 5.5 proved half of 36 verification tasks using about 40% fewer tokens than Opus 5.
- Sharing proof work cut token use by 17% compared with agents working alone.
- Theorem offers to run the pipeline on other open-source projects and is publishing a Claude skill.
One catch: Proofs can require hundreds of millions of tokens. Coverage is limited to specified crash properties for inputs up to 64 MB, under a single-threaded, static RISC-V Linux setup with a fixed memory budget. This does not establish that entire libraries are bug-free.
Sources: anthropic.com
Top News · Reported · ctee.com.tw · translated from Chinese
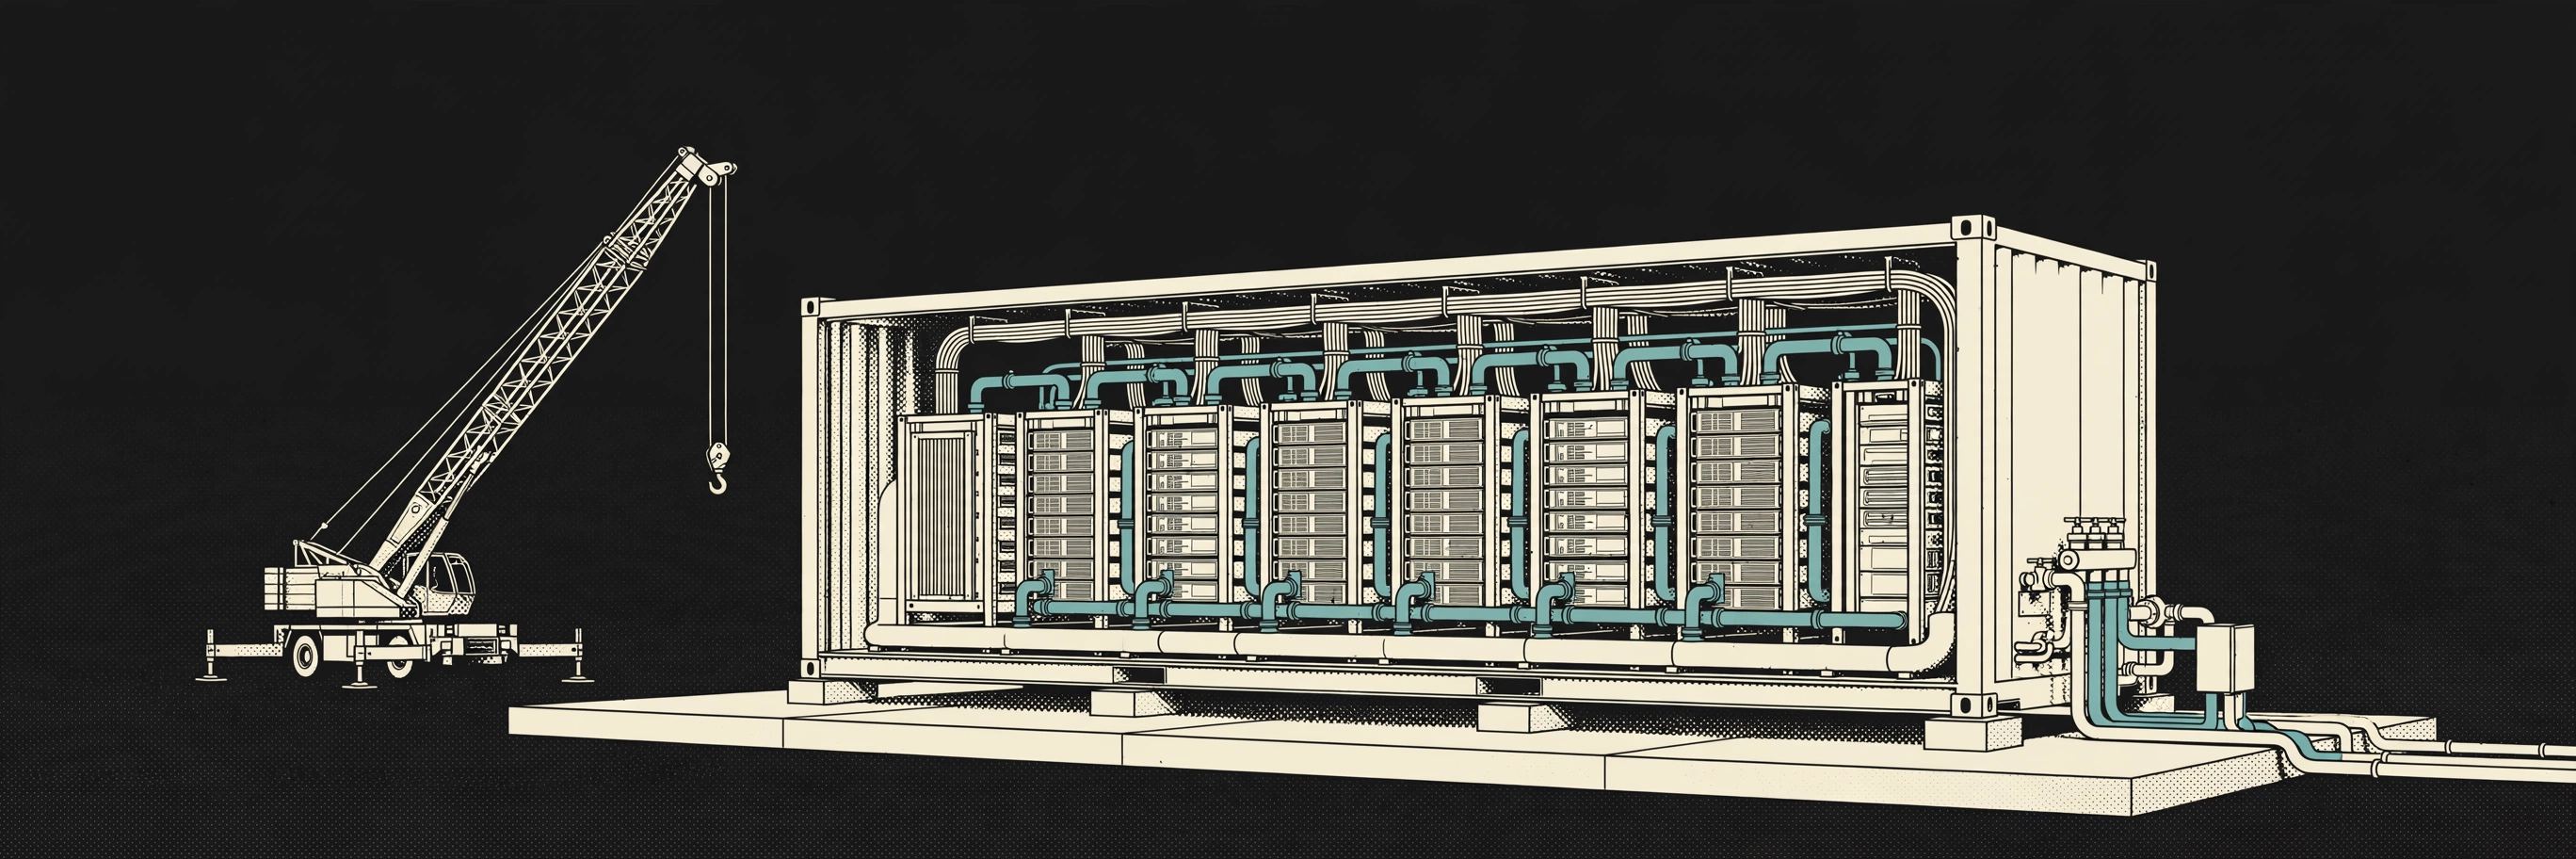
NVIDIA's new DSX POD combines Vera Rubin compute, networking, power, and liquid cooling in a modular containerized system. NVIDIA says moving integration into supplier factories can cut deployment from six months to as little as 14 days once site facilities are ready.
Here's what changed:
- A design unit connects seven liquid-cooled compute racks with about 17 km of Spectrum-X network cabling.
- Wiring, validation, and burn-in happen before shipment, reducing on-site connection and troubleshooting work.
- The system uses 800 VDC power, and Vera Rubin supports coolant temperatures up to 45°C.
- Ingrasys, a Hon Hai subsidiary, is a global partner for Vera Rubin-based modular AI factories.
One catch: The deployment timeline assumes site facilities are ready. Global delivery is expected in early 2027.
Sources: ctee.com.tw
Top News
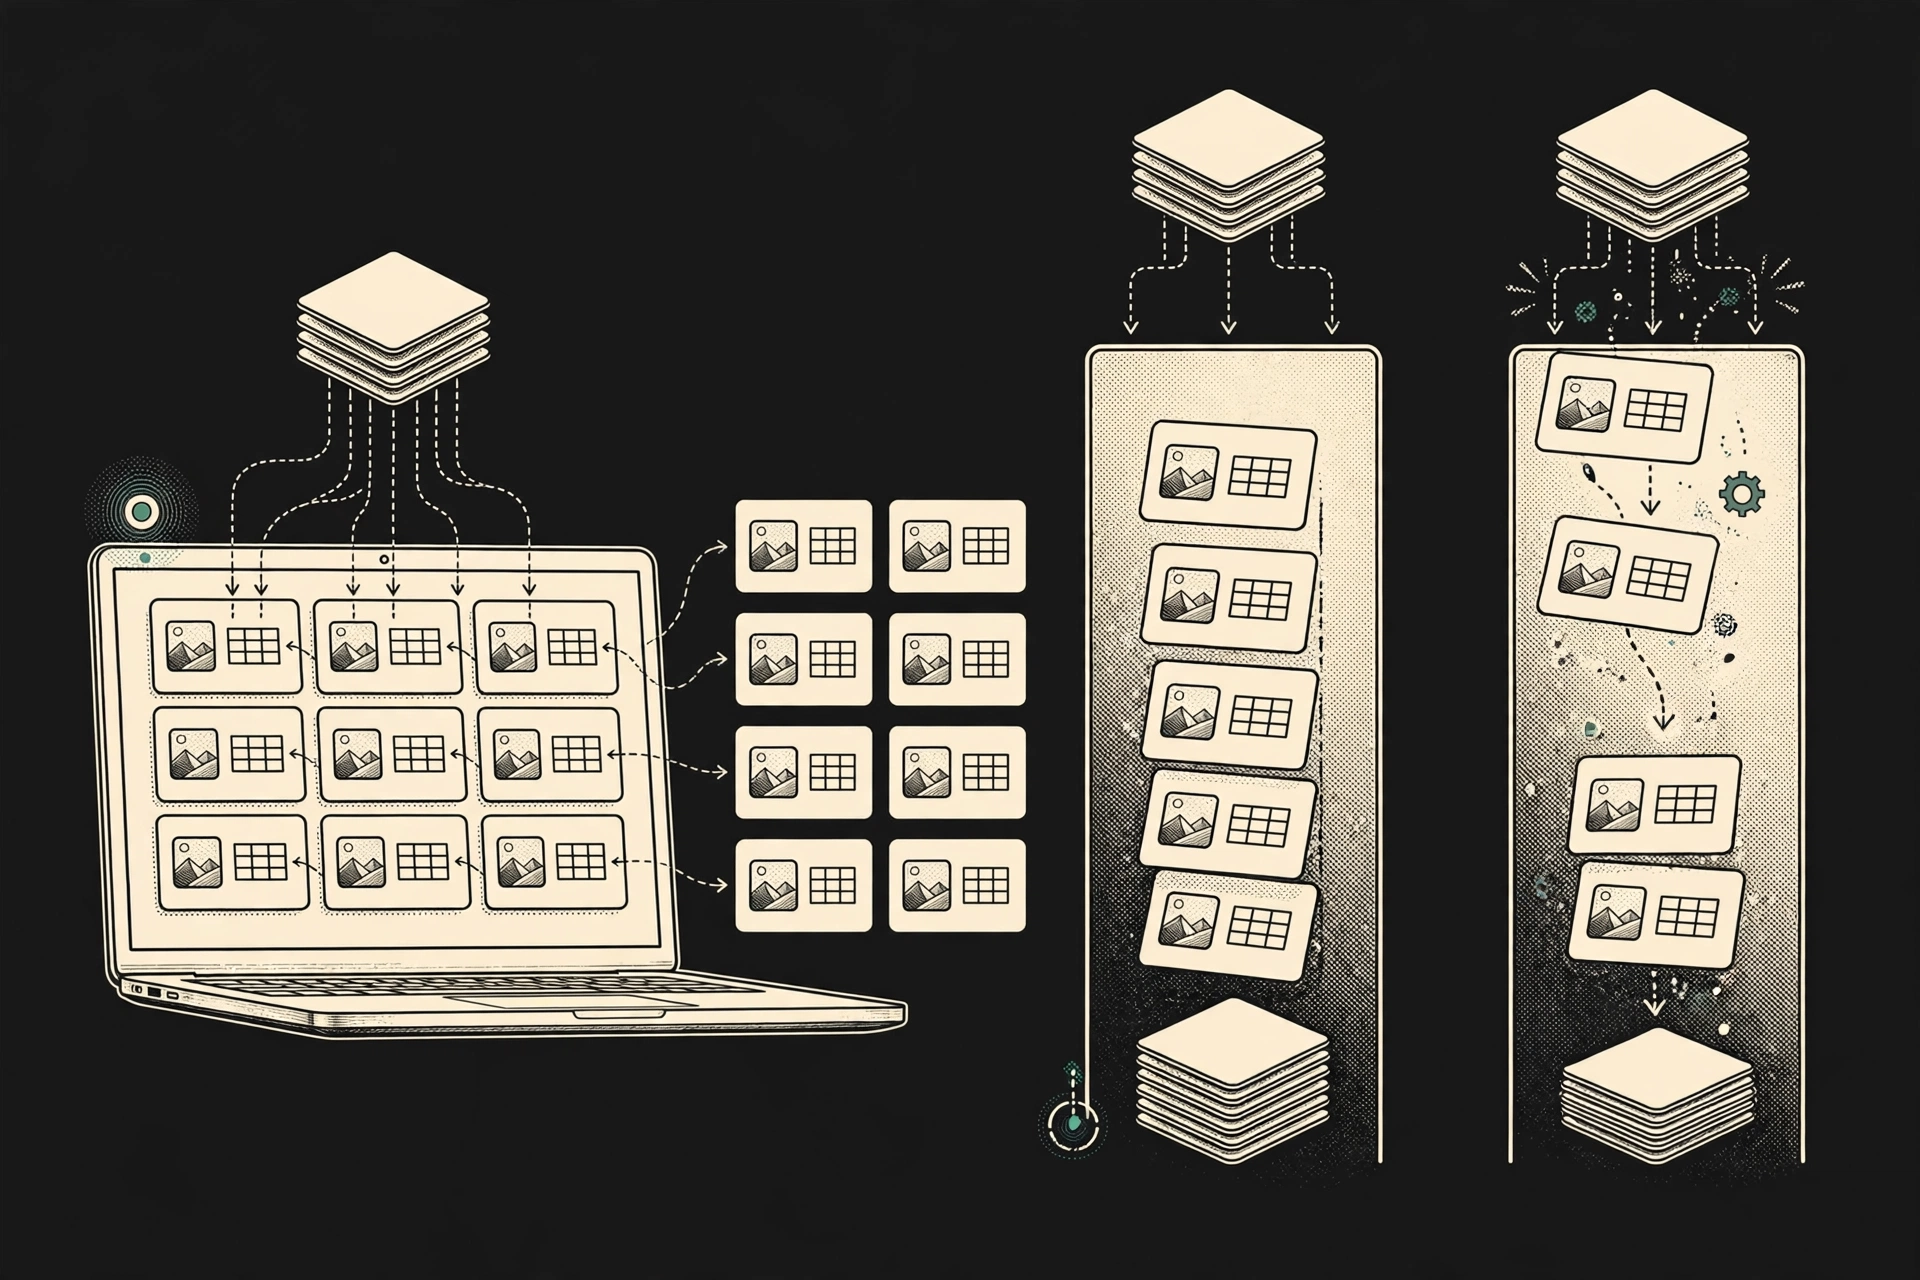
If you need typed answers from text and images, OpenAI's Decisions API is now generally available with gpt-6-luna. OpenAI claimed it was 10× faster than the Responses API when it announced the public beta. The GA release doubles the question limit per request and adds shared-input caching, image instructions, and structured-data input.
Here's what changed:
- Requests support up to 400 questions, up from the public-beta limit of 200.
- Shared input can be cached across requests to get prompt-cache discounts on repeated input.
- Images can appear in individual question instructions, so each question can carry its own image.
- Structured data can be sent through
input_json.
Why care? You can batch more questions into each call and reuse shared context across requests at discounted prompt-cache rates.
Try it: Send a request to v1/decisions using gpt-6-luna.
Sources: developers.openai.com
Also in this issue
Signals
- Modular releases MAX source code for royalty-free commercial use across CPUs and GPUs
- Modal releases Spindle, an open-source Tinker-compatible training server charging for GPU time instead of tokens
- Ollama adds Recursive Flint coding model with a 262K-token context window on macOS · 8 Stars today
- CoreWeave ships NVIDIA GB300 NVL72 instances, reporting over 6x H100 throughput per GPU on DeepSeek R1 · Official · coreweave.com
- Amazon SageMaker adds training session APIs for custom LLM training loops without managing GPUs
- Claude Opus 5.5 passes 58% of runs on FrontierCS 2 computer science research benchmark · 2 Upvotes