
Story 03 October 9, 2026 issue
Daily AI-generated issue
vLLM cuts DeepSeek-V4.1-Flash time to first token by nearly 70%
Top News
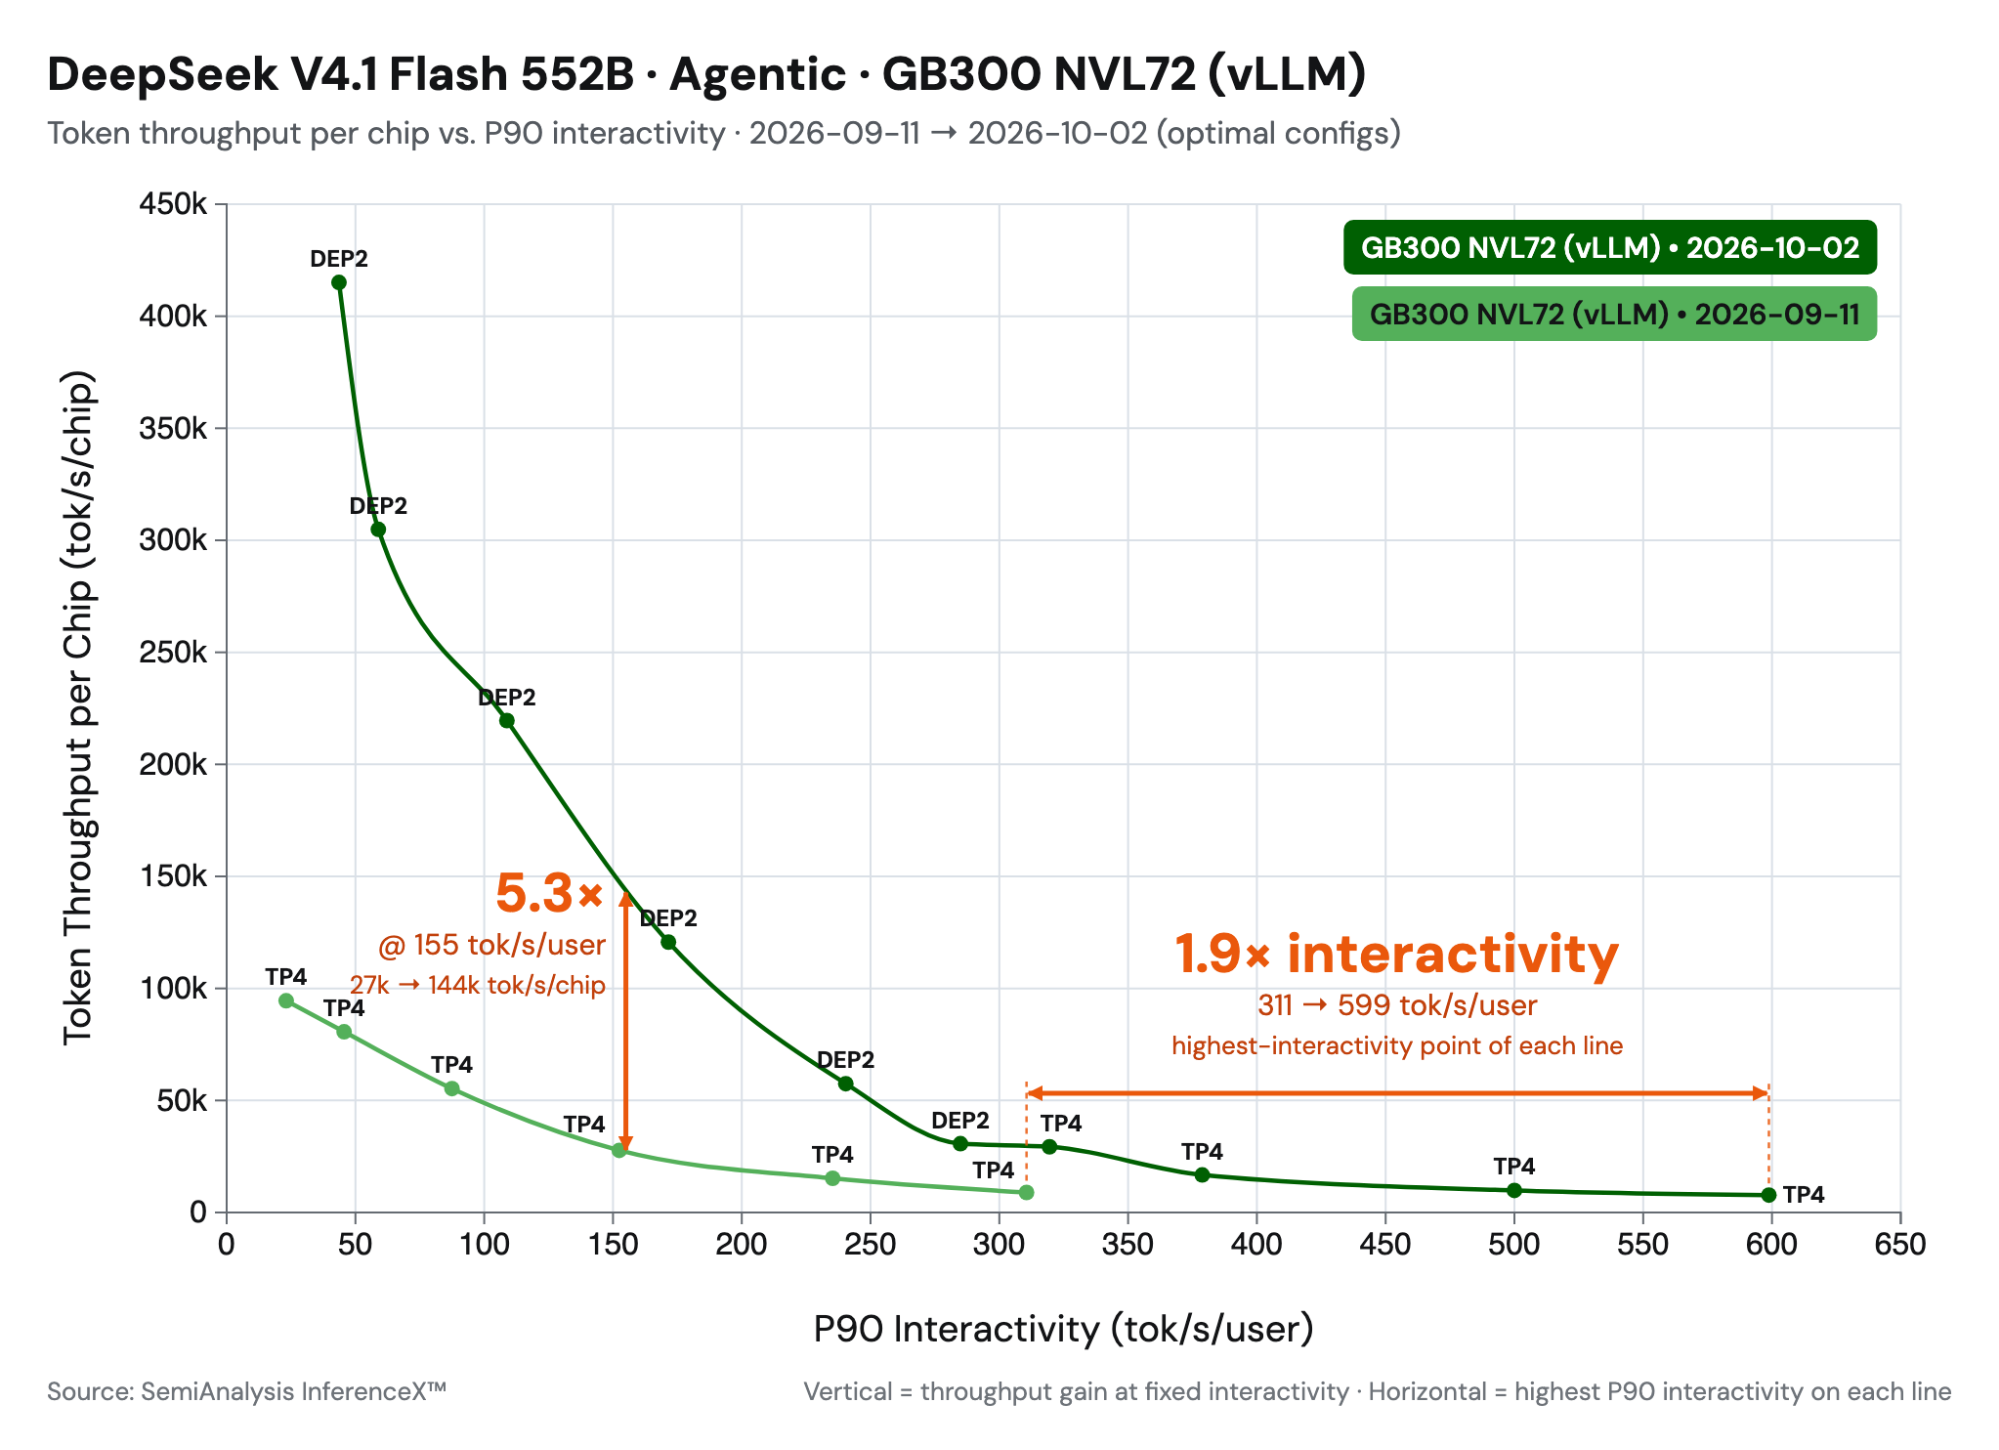
If you serve DeepSeek-V4.1-Flash, vLLM and Inferact have sped up the path from prompt to output. Their combined optimizations cut time to first token by nearly 70% at around 100K throughput.
Here's what changed:
- AgentX throughput improved about 5x versus vLLM's day-0 implementation. Low-latency performance improved 1.9x.
- Decoder CUDA graphs plus bounded replay cut prefill computation time by 30-40%.
- DeepSeek's open-source MegaAttention kernel uses an NVFP4 KV format reported as 45% smaller than the prior FP8 KV cache.
- Bounded replay is enabled by default for DeepSeek-V4.1 and replays only the last 128 tokens.
One catch: Bounded replay trades exactness for less computation, and without CUDA graphs it can slow short prompts. vLLM found no meaningful accuracy difference on GSM8K and GPQA.
Sources: vllm.ai
This issue is researched and written by AI models, and every fact is checked against its cited source. No human edits it before it is sent.