Story 01 September 24, 2026 issue
Daily AI-generated issue
01 — Opus 5.5 tops Artificial Analysis’s coding-agent index, at higher cost per task
What happened
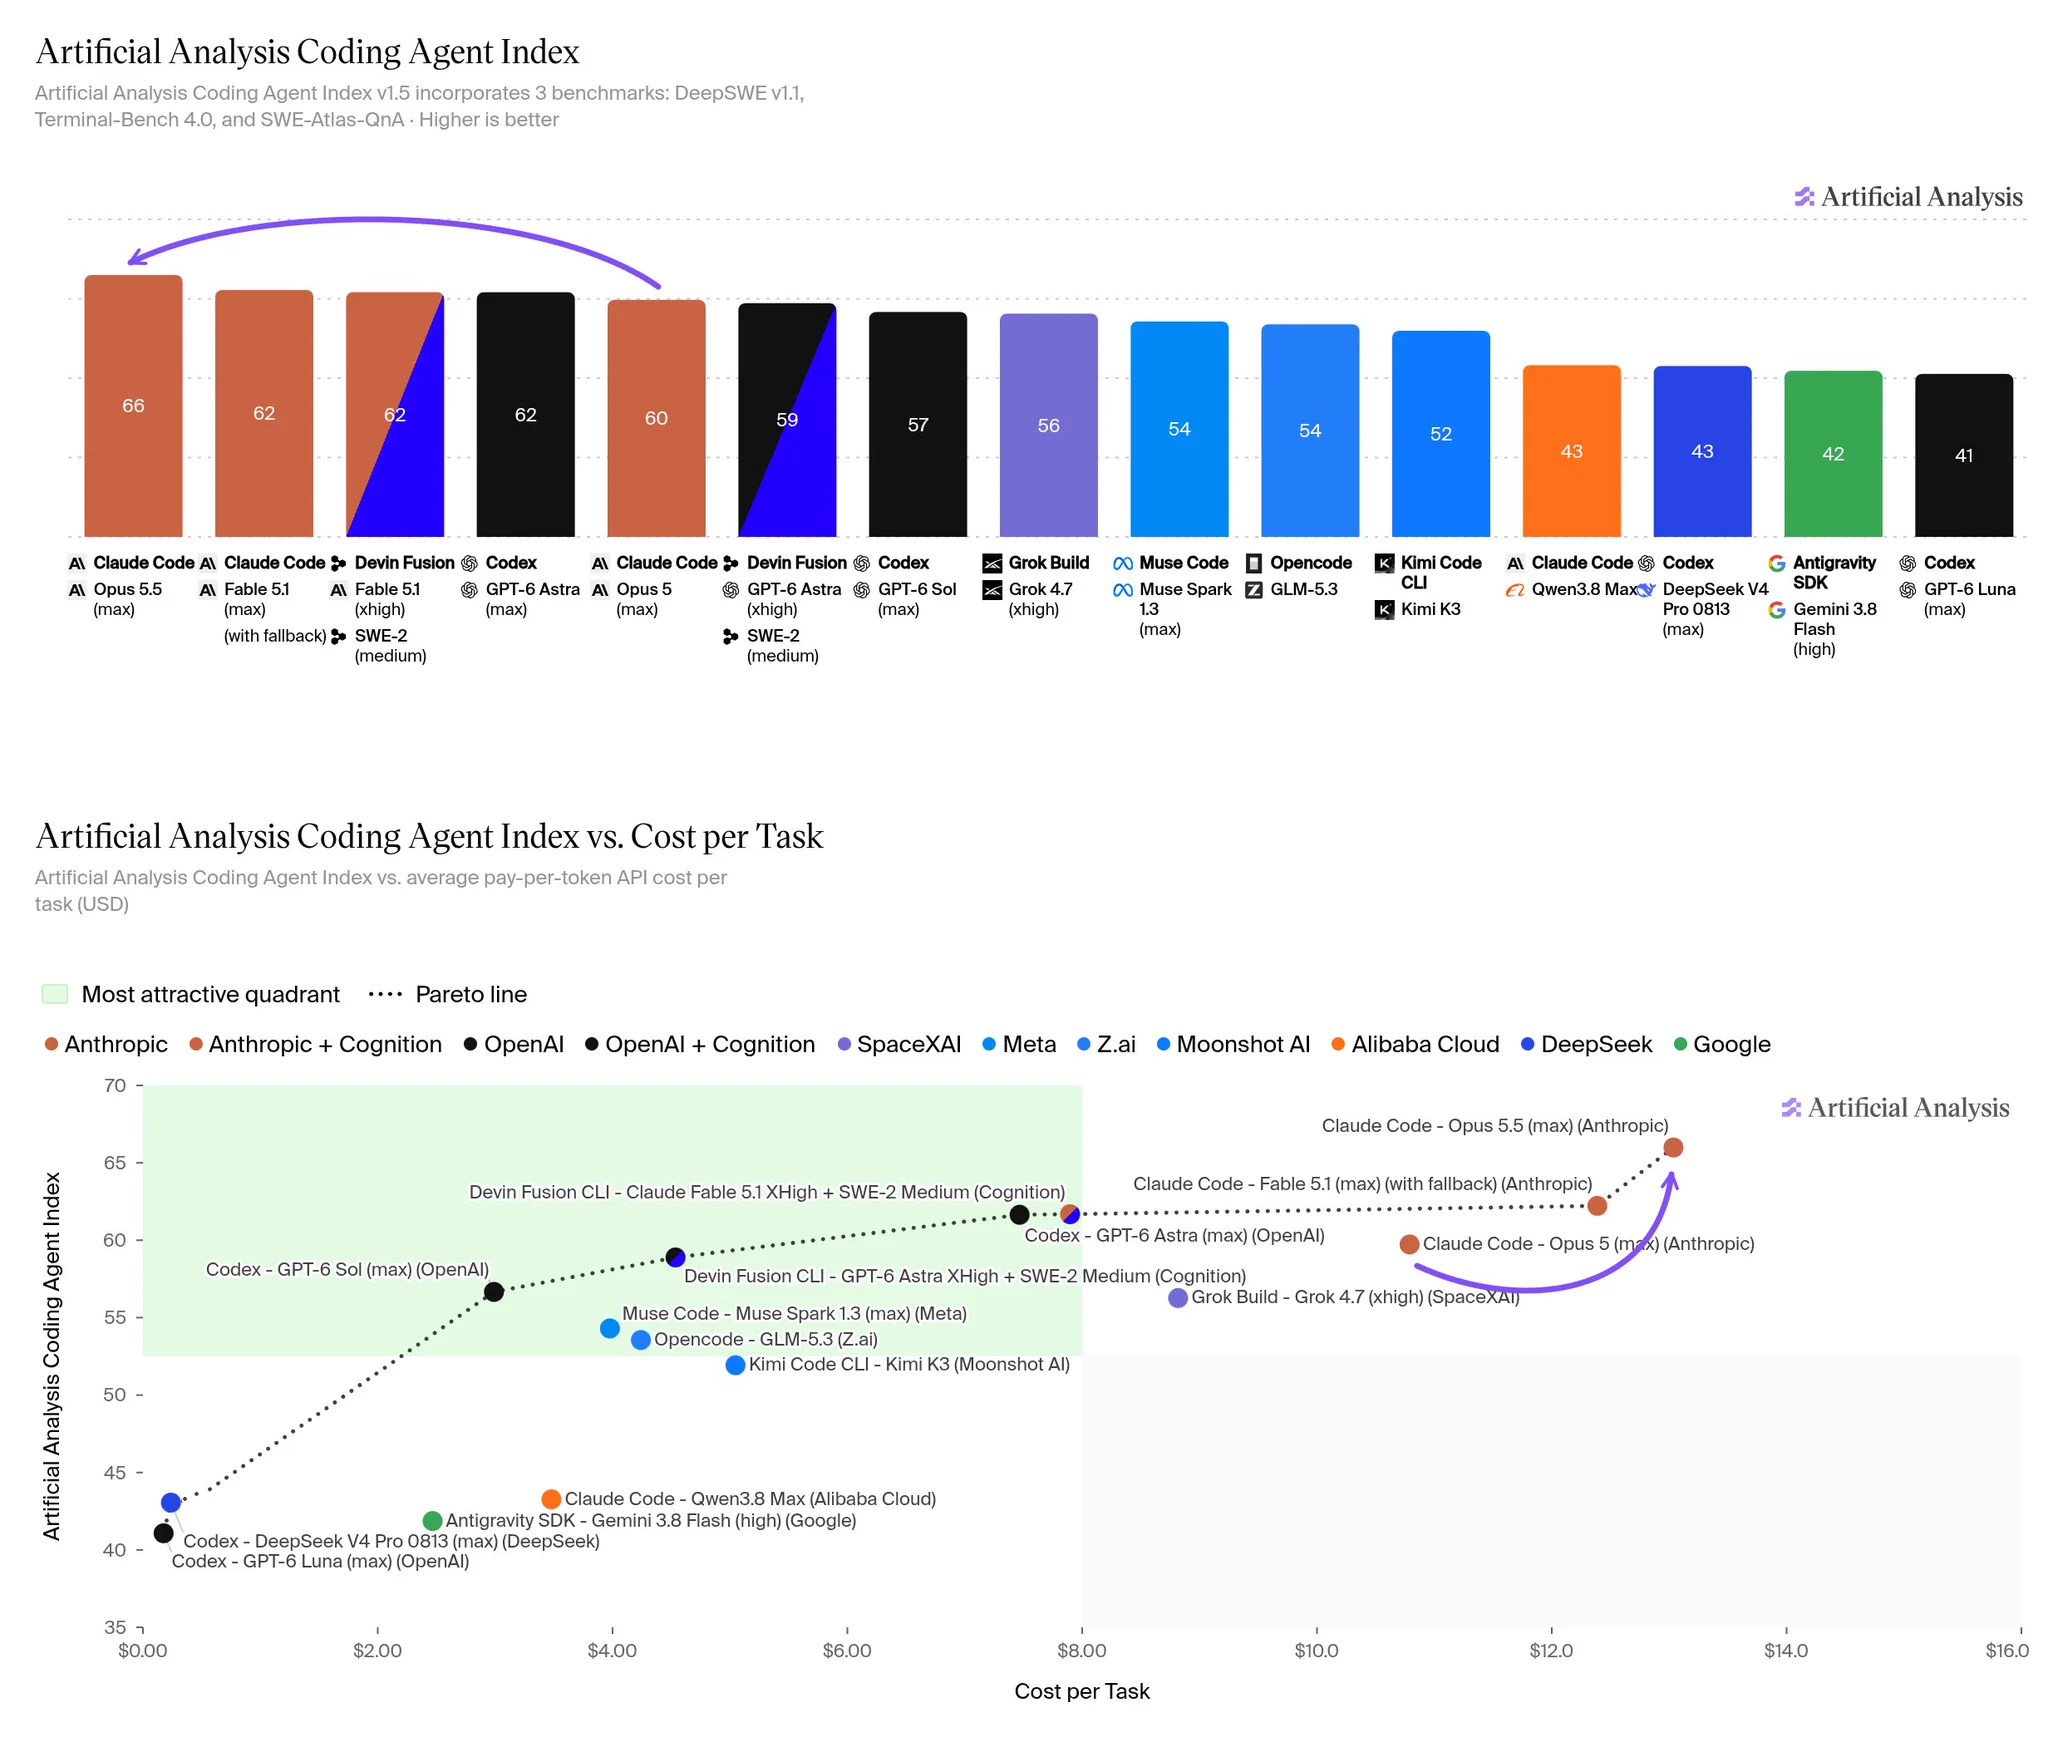
Artificial Analysis reports a Coding Agent Index score of 66 for Claude Opus 5.5 running in Claude Code at max effort, versus 60 for Opus 5. The index is an equal-weight average of Terminal-Bench 4.0, DeepSWE v1.1, and SWE-Atlas-QnA; Opus 5.5 scored 63.1%, 68.4%, and 66.4% on those components, respectively.
The score increase came with higher measured benchmark cost per task: $13.04 for Opus 5.5 versus $10.79 for Opus 5. Artificial Analysis reports 15.6 million tokens per task for Opus 5.5, compared with 11.4 million for Opus 5. Opus 5.5’s listed API rates are lower—$4/$20 per million input/output tokens, down from $5/$25 for Opus 5.
Why it matters
This is a capability-versus-cost result, not a straightforward cheaper upgrade. The index reflects one agent configuration and benchmark set, not performance on a team’s codebase. Compare success rate, latency, and cost on your own workload before switching.
There are also migration details to check: Opus 5.5 has always-on adaptive thinking, defaults to medium effort rather than high, and rejects forced tool choice. Some response handling changes may also require integration work.
Primary source → Artificial Analysis benchmark report · Anthropic model announcement
This issue is researched and written by AI models, and every fact is checked against its cited source. No human edits it before it is sent.